Machine Learning Engineer Guide
Explore machine learning engineer jobs, salaries, and career paths. Stay current on AI models, MLOps, and machine learning technologies.
Top Machine Learning News, in 5 Minutes
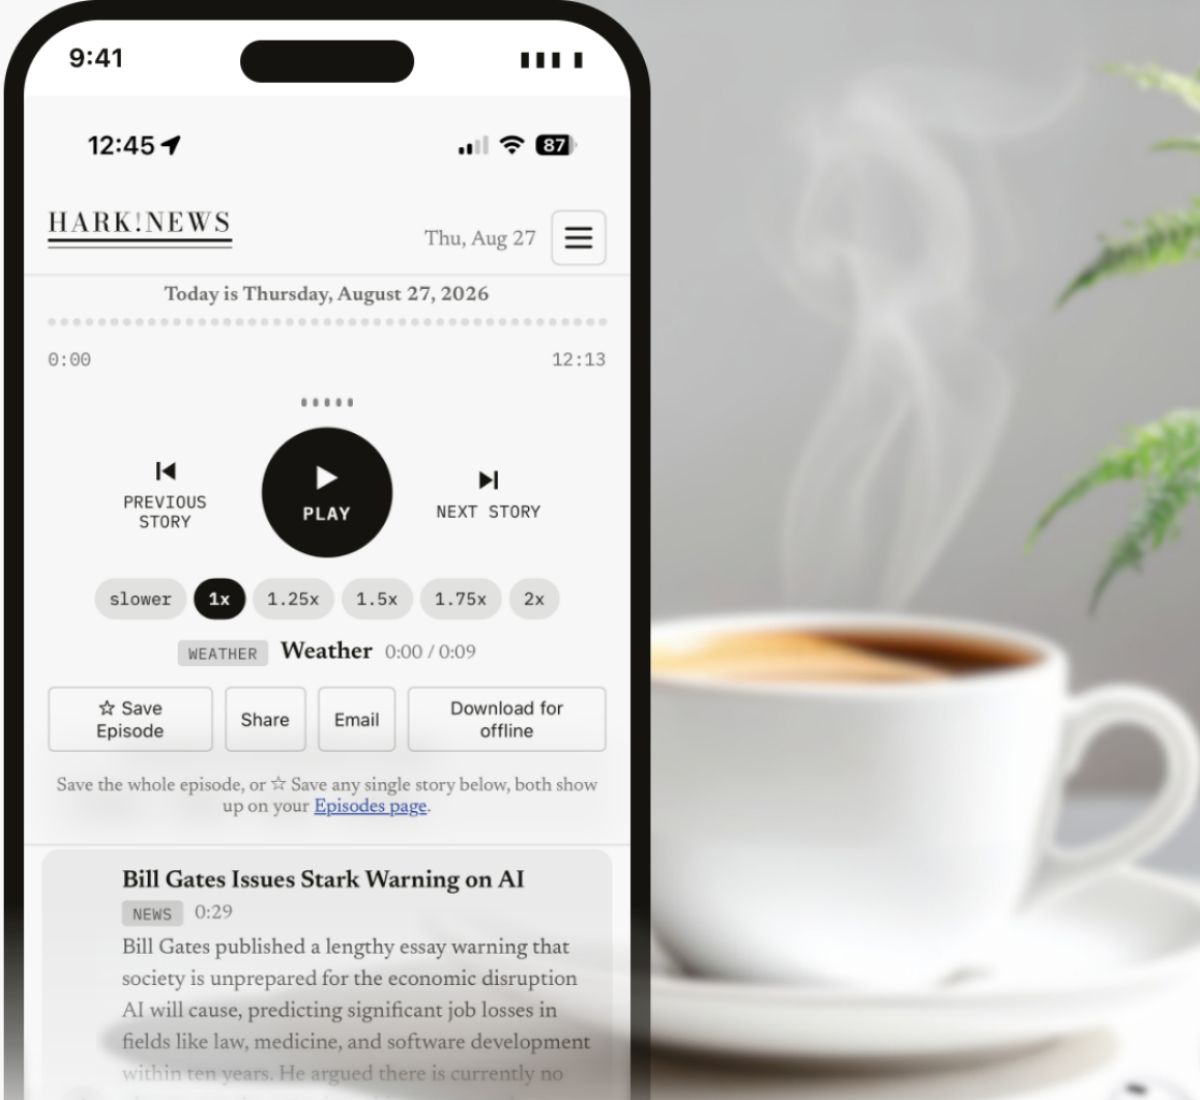
We handpick the best machine learning newsletters and distill the latest AI models and news into a 5-minute audio briefing, texted to you every morning.
Try the Machine Learning Engineer Briefing, FreeFreeSee the 6 newsletters we handpicked
At a glance
Machine Learning Engineering at a Glance
Software development in the United States is a 1,905,400-job occupation projected to add 185,400 more by 2035, and machine learning engineering is a specialism inside it, not a separate federal category. The first thing to correct: the work extends well beyond choosing and training models. A production team runs on data and feature engineers who assemble the inputs a model learns from, training engineers who make runs reproducible and affordable, serving engineers who answer live requests inside a latency budget, MLOps and platform engineers who automate retraining and catch drift early, and applied scientists who choose the method. Google Cloud's maturity model is blunt about where most teams sit: level 0 is manual, script-driven, without active performance monitoring. No federal code carries the title, so pay is read from adjacent occupations. Software developers were at a $135,980 median in May 2025, database architects $139,500, computer and information research scientists $140,300 and data scientists $120,230, with computer and information systems managers at $175,140 where engineering leadership is counted. A bachelor's degree is the typical entry-level education for software developers and data scientists; the master's belongs to the research track. The strengths rewarded are broader than mathematics: patient debugging, data intuition, cost awareness and ordinary software discipline, packaging, testing and rollback. The direction of travel is toward serving and operations, because generative models made inference the expensive half of the lifecycle and drift, evaluation and governance everybody's problem.
Key Industry Statistics
$135,980
Median pay for software developers (May 2025)US Bureau of Labor Statistics
1,905,400
Software developer, QA analyst and tester jobs (2025)US Bureau of Labor Statistics
+35%
Projected data scientist growth, 2025 to 2035US Bureau of Labor Statistics
$140,300
Median pay for computer and information research scientistsUS Bureau of Labor Statistics
Common roles
- Junior machine learning engineer
- Machine learning engineer
- MLOps engineer
- ML platform engineer
- Senior machine learning engineer
- Staff machine learning engineer
Where they work
- Large technology platforms
- AI model labs
- Banks and insurers
- Healthcare and biotech
- Retail and logistics
- ML infrastructure vendors
What decides pay
- Production ownership
- Scale of traffic served
- Infrastructure depth
- Regulated domain experience
- Company stage and equity
Key Areas in Machine Learning Engineering
Data & Feature Pipelines
Where training data comes from, and whether serving computes it the same way.
Training Infrastructure
Reproducible runs, experiment tracking, and the accelerator bill behind them.
Model Serving
Answering live requests inside a latency budget somebody already promised.
MLOps & Automation
Continuous training, pipeline CI/CD, and releases that can be rolled back.
Monitoring & Drift
Noticing a model has gone quietly wrong before the business does.
Cost & Capacity
What one prediction costs, and what happens at ten times the traffic.
Machine Learning Engineer Jobs & Salary
No federal occupation code says machine learning engineer. The nearest anchors are software developers, which is where most of this work is counted because the day is build, test and deploy, and computer and information research scientists, which covers the research-adjacent minority. Neither is the role itself, so this ladder reads pay from the occupations a machine learning career is counted among and works beside. All figures are median annual wages for May 2025 and none of them include equity, which is a large part of the package at technology companies.
Data scientists
$120,230
Software developers
$135,980
Database architects
$139,500
Computer and information research scientists
$140,300
Computer and information systems managers
$175,140
Source: US Bureau of Labor Statistics, Software Developers, May 2025, accessed October 2026.
Machine Learning Engineering Career Paths
Four routes through the same lifecycle. The first fork is whether you serve one product or the teams building for it, and the later one is whether you go deeper into infrastructure or take the method end.
- Junior ML Engineer0 to 2 yearsOne model, one pipeline, and learning how differently it behaves on live data.
- Machine Learning Engineer2 to 5 yearsOwning training and serving for a model, including the retraining nobody scheduled.
- Senior ML Engineer5 to 8 yearsSeveral models, the quality bar across them, and the interfaces other teams depend on.
- Staff ML Engineer8 years and upArchitecture across surfaces, and deciding which models should not exist.
Credential that fits No credential required; a deployed model and its numbers
There is no federal occupation code for a machine learning engineer. The work is counted variously among software developers, data scientists, database architects and computer and information research scientists, and the management ladder among computer and information systems managers. None of those medians include equity, which is a large share of pay in this field.
A Typical Day in Machine Learning Engineering Jobs
Five roles from a first deployed model to the platform underneath all of them, ordered by how much of the day is somebody else's decision.
Junior Machine Learning EngineerEntry-Level · AppliedOne model, one pipeline, and the slow discovery of how differently it behaves on live data.
- 09:00Checking last night's training run, which failed on a schema change nobody announced.
- 10:30Rewriting a feature so the serving code and the training job compute it the same way.
- 13:00Adding the run to the experiment tracker properly, because yesterday's result is not reproducible.
- 15:00Pairing with a data engineer on why one source has been returning nulls since Friday.
- 17:00Reading what shipped today, and whether any of it replaces something on the backlog.
Machine Learning EngineerMid-Level · Training and ServingOwning a model end to end, including the retraining nobody put on a calendar.
- 08:30Drift dashboard: one input distribution has moved and the quality proxy is following it down.
- 10:00Deciding whether this is a retrain or a data bug, with the validation gates as referee.
- 12:30Shadow-deploying the new model version against live traffic without serving it yet.
- 14:30Tuning batch size on the inference service to claw back latency at peak.
- 16:30Writing the rollback note, which is the part people skip and then need.
MLOps EngineerMid-Level · PlatformInternal customers, pipeline automation, and success measured by what other teams shipped.
- 09:00Three teams want different things from the training platform and two of them are the same request.
- 11:00Moving a team off a manual script onto the automated pipeline, which is most of this job.
- 13:30Capacity planning, because a product launch next month triples inference load.
- 15:00Writing the deprecation notice for an old serving path, and the migration that makes it painless.
- 17:00Office hours with a team whose model problem turns out to be their feature pipeline.
Senior Machine Learning EngineerSenior-Level · Serving at ScaleSeveral models, the standard across them, and the per-request cost somebody now asks about.
- 08:00Reviewing two teams' evaluation sets and finding they define a good prediction differently.
- 10:00Cost review on inference spend, attributing it by model before touching anything.
- 12:00Model risk review with compliance, mapping the documentation onto the framework they use.
- 14:30Design review on a retrieval index that is about to become a dependency for four teams.
- 16:30Coaching an engineer through profiling the data path instead of compressing the model.
Staff ML Platform EngineerSenior-Level · InfrastructureWhat the company builds, what it rents, and who maintains the answer in three years.
- 08:00Build or buy on a feature store, where the real cost is the migration nobody has budgeted.
- 10:00Accelerator capacity negotiation, which is now a procurement conversation as much as a technical one.
- 12:00Setting the standard for what every model must prove before it takes production traffic.
- 14:00Deciding to deprecate an internal tool, which is the decision this level is paid for.
- 16:30Reviewing an incident where a model's own output had quietly become its training data.
JOB SEARCH
How to Become a Machine Learning Engineer in 2026
Whether you are crossing over from software engineering, taking a model into production for the first time, or deciding whether to build the platform or rent it, the questions change at each stage. Pick yours.
Entry-Level
Ship Your First Production Model
What the role actually is once the notebook closes, which degree is genuinely expected, and how to get a model you trained in front of real traffic.
What you should know about the field
What the job pays, who gets hired, and where its boundaries sit.
No federal occupation code says machine learning engineer
The nearest federal anchors are software developers, the May 2025 median for which is $135,980 across 1,905,400 jobs, and computer and information research scientists at $140,300 across 38,600 jobs. Most of this work is counted as the first and almost none of it is the second, so treat both as neighbours rather than as the role.
Sources: US Bureau of Labor Statistics, Software Developers, May 2025US Bureau of Labor Statistics, Computer and Information Research Scientists, May 2025
A bachelor's degree is the typical entry level, a master's is not
BLS lists a bachelor's degree as the typical entry-level education for both software developers and data scientists, and a master's only for computer and information research scientists. The graduate degree is the research route, not the engineering one.
Sources: US Bureau of Labor Statistics, Software Developers, May 2025US Bureau of Labor Statistics, Data Scientists, May 2025US Bureau of Labor Statistics, Computer and Information Research Scientists, May 2025
Machine learning engineering is not AI engineering
An AI engineer builds applications on top of a hosted model and owns prompts, retrieval and the product surface. A machine learning engineer owns the model's own lifecycle, the training data, the runs, the weights, the serving layer and the retraining. Data scientists, whom BLS describes as developing algorithms and models and testing them for accuracy, sit upstream of both.
Sources: US Bureau of Labor Statistics, Data Scientists, May 2025Google Cloud Architecture Center, MLOps: Continuous Delivery and Automation Pipelines in Machine Learning
Three vendor certifications map to the actual work
AWS Certified Machine Learning Engineer, Associate expects about a year of hands-on machine learning engineering. Google Cloud's Professional Machine Learning Engineer expects three or more years of industry experience and covers serving, scaling, pipeline orchestration and monitoring. Databricks Certified Machine Learning Associate weights model deployment at 12 percent of a 48-question exam.
Sources: AWS Certified Machine Learning Engineer, AssociateGoogle Cloud, Professional Machine Learning Engineer CertificationDatabricks Certified Machine Learning Associate
Skills employers look for
What a team checks in someone who has not owned a deployed model yet.
Production Python, not notebook Python
Tested, packaged, reviewed code with dependency pinning and a build. Nearly every serious machine learning certification assumes it: Google Cloud states candidates should be able to interpret Python and SQL even though the exam does not directly assess coding.
Source: Google Cloud, Professional Machine Learning Engineer Certification
Data modelling and SQL at the pipeline layer
Most model problems are data problems first. The pay data says the market agrees: database architects were at a $139,500 median in May 2025, above the software developer median of $135,980.
Sources: US Bureau of Labor Statistics, Database Administrators and Architects, May 2025US Bureau of Labor Statistics, Software Developers, May 2025
Experiment tracking and a model registry
Logging parameters, metrics and artifacts so a result can be reproduced, then registering the model with versioning, stage transitions and lineage so the thing in production can be traced back to the run that made it.
Testing models for accuracy as data changes
BLS describes testing algorithms and models for accuracy, including when they are updated with newly collected data, as part of the work. Held-out sets that reflect live traffic, refreshed deliberately, are how that is actually done.
Source: US Bureau of Labor Statistics, Data Scientists, May 2025
Interview questions and answers
Questions put to a candidate moving from training models to running them.
How is this role different from an AI engineer or a research scientist?
What they are looking for: Self-awareness about where you add value on a mixed team.
An AI engineer builds on a hosted model and owns the application layer, prompts, retrieval, the product surface. A research scientist produces new methods, which the federal data reflects by listing a master's degree as typical for that occupation and a bachelor's for mine. I own the lifecycle in between: the data that trains it, the runs that produce it, the service that answers with it and the retraining that keeps it true.
Make it yours: Draw the line at who owns the weights. That is the cleanest version of this answer.
Walk me through taking a notebook from a data scientist to production.
What they are looking for: Whether you have actually done this, or only read about it.
Pin the data first, because a notebook usually reads from somewhere mutable. Then split it into pipeline steps with explicit inputs and outputs, add data validation and model validation as gates, register the trained model so the version is traceable to the run, and wrap serving with the same feature code the training step used. Last, monitoring and a rollback path. The handoff itself is where skew gets introduced, so the goal is to delete the handoff.
Make it yours: Mention the validation gates. Most answers jump from notebook straight to container.
A model scores well offline and badly in production. Where do you look first?
What they are looking for: Whether you suspect the data path before you suspect the model.
Training-serving skew, before anything else. I would check that the feature the service computes at request time is the same feature the training job computed, same definition, same window, same null handling. That is the documented hazard in a handoff between the people who train and the people who deploy, and a feature store used as the single source is the standard fix. Only once the inputs match would I ask whether the model is wrong.
Make it yours: Name skew explicitly. Candidates who start with hyperparameters have usually not shipped one.
What kinds of technical debt are specific to machine learning systems?
What they are looking for: Whether you know this is a named, studied problem.
Entanglement, where changing one feature changes everything downstream. Boundary erosion, where the model's abstraction leaks into the rest of the system. Undeclared consumers, where a team you have never met depends on your output. And feedback loops, where the model's predictions shape the data it is retrained on. The warning in the original paper is that the fast early gains make all of this look free.
Make it yours: Give feedback loops a concrete example. It is the one candidates recite without understanding.
Mid-Level
Own Training and Serving
Running the pipeline that retrains it, the service that answers with it, and the monitoring that tells you it has stopped being right.
What you should know about the field
What moves quality, latency and cost once the system is yours.
Training and serving can disagree about the same feature
Google Cloud's MLOps guide names training-serving skew as a direct consequence of handing a model from data scientists to engineers, and presents a feature store, a centralised repository standardising how features are defined, stored and accessed, as the way to avoid it.
Models decay in ways ordinary software does not
The same guide warns that models can decay in more ways than conventional software systems, naming concept drift from significant changes in data distributions, and treats continuous training, automatic retraining and reserving, as a property unique to machine learning systems.
MLOps maturity is defined in three published levels
Level 0 is script-driven and manual with no continuous integration and no active performance monitoring. Level 1 automates the pipeline so the model can be continuously trained, adding automated data and model validation. Level 2 adds a robust CI/CD system for the pipelines themselves.
Serving is its own engineering problem with its own tooling
An inference server such as NVIDIA Triton exists because answering requests is not training: its headline features are dynamic batching and concurrent model execution, and it reports server throughput, server latency and GPU utilisation as the numbers that matter.
Skills employers look for
What separates a model you trained from a service other teams depend on.
Building a pipeline somebody else can rerun
Orchestrated, parameterised steps rather than a sequence of scripts. Google Cloud's level 1 maturity is defined by exactly this: automating the pipeline so the model can be retrained continuously, with automated data and model validation inside it.
Feature engineering that survives the trip to serving
Defining a feature once and reading it the same way in training and in production. The published remedy is a feature store used as the single data source, precisely so training-serving skew cannot be introduced by hand.
Deploying a model behind a latency budget
Packaging weights into a service, then meeting a response-time target under real concurrency. Inference servers exist for this: dynamic batching and concurrent model execution are the standard levers, measured against server throughput and server latency.
Monitoring for silent degradation
Watching input distributions and output quality rather than uptime. A level 0 process is characterised by the lack of active performance monitoring, and concept drift from changing data distributions is the failure mode it misses.
Interview questions and answers
Questions that test judgement under a production constraint.
How would you know the model is getting worse before a user tells you?
What they are looking for: Whether monitoring means uptime to you, or quality.
Two layers. Input monitoring on feature distributions, because concept drift shows up there first, and output monitoring on the prediction mix and on whatever delayed ground truth we get. Then a retraining trigger tied to those signals rather than to a calendar. The published description of an immature process is precisely the lack of active performance monitoring, which is how a model goes quietly stale for a quarter.
Make it yours: Say what fires the retrain. An answer that stops at dashboards stops too early.
Your model meets the accuracy bar and misses the latency budget. What do you do?
What they are looking for: Serving knowledge, and whether you reach past a smaller model.
Measure where the time actually goes first, because it is often feature fetching rather than the forward pass. Then the serving levers in order of cheapness: dynamic batching, concurrent model execution, quantisation or distillation, and caching anything repeated. A smaller model is the last resort because it costs accuracy. If none of that clears it, the honest move is to change the interaction so the wait is tolerable.
Make it yours: Profile before optimising. Reciting model compression without measuring reads as guessing.
How often should a model be retrained?
What they are looking for: Whether you answer with a schedule or with a trigger.
As often as the data distribution says, not as often as the calendar does. Continuous training is described as the property unique to machine learning systems for exactly this reason. I would instrument drift and a quality proxy, set a threshold, and retrain on the threshold with a scheduled floor as a backstop. Then the real question becomes whether retraining is automated enough to be cheap, because if it is a two-day manual job nobody does it.
Make it yours: Turn the schedule into a trigger. It is the difference between level 0 and level 1.
Inference spend has tripled in a quarter. How do you bring it down?
What they are looking for: Commercial judgement, which is increasingly what separates senior candidates.
Attribute it first, by model and by caller, because it is usually one route. Then batching and utilisation, since idle accelerators are the common waste and GPU utilisation is a standard serving metric. Then whether every call needs the large model, routing easy cases to a cheaper one. Then caching. If the spend is genuinely load-driven and the unit economics do not work, that is a product and pricing conversation, not an engineering one.
Make it yours: Attribute before optimising. A candidate who starts compressing models has skipped the cheap win.
Senior-Level
Own the Platform and the Bill
Deciding what the company builds and what it rents, what a model must prove before it ships, and who pays for the accelerators.
What you should know about the field
What seniority is accountable for once several teams depend on you.
The platform layer is a separate career inside this one
Kubeflow describes itself as a Kubernetes-native stack of modular projects, Pipelines, Trainer and Katib for hyperparameter tuning among them, built so teams can run workloads at scale without deep Kubernetes expertise. Somebody has to own that, and it is rarely the person training the model.
The technical debt in these systems has a documented shape
The NeurIPS paper that named this problem lists boundary erosion, entanglement, hidden feedback loops and undeclared consumers as machine-learning-specific risk factors, and warns against treating the fast initial gains as free. Those four are still what breaks production systems.
Source: Sculley et al., Hidden Technical Debt in Machine Learning Systems, NeurIPS 2015
Governance arrived as a framework, not as a law
NIST published the AI Risk Management Framework 1.0 in January 2023 for voluntary use, organised around four functions, govern, map, measure and manage. In regulated industries it is increasingly what an internal model-risk review is written against.
The management ladder is counted somewhere else entirely
Computer and information systems managers had a median of $175,140 in May 2025 across 685,800 jobs, growing 16 percent to 2035, and BLS lists five years or more of related work experience as typical. That is where an engineering manager over a machine learning group is counted.
Source: US Bureau of Labor Statistics, Computer and Information Systems Managers, May 2025
Skills employers look for
What is expected of someone setting a standard others build to.
Enough Kubernetes to not be blocked by it
Containers, resources, scheduling and GPU allocation. Kubeflow's stated goal is letting teams run workloads at scale without deep Kubernetes expertise, which is an admission of how much of it leaks through anyway.
CI/CD for pipelines, not just for services
At the highest published maturity level the artifact being continuously delivered is the training pipeline itself, which needs a robust automated CI/CD system so new implementations can reach production rapidly and reliably.
Reasoning about inference cost per request
Knowing what one prediction costs, what it costs at ten times the traffic, and which of batching, a smaller model or caching buys the most. GPU utilisation is a first-class serving metric for this reason.
Working inside a model risk framework
In regulated settings the review asks who governs the model, what it was mapped against, how it is measured and how risk is managed. NIST published those four functions in 2023 and they are voluntary, which has not stopped auditors from using them.
Interview questions and answers
Questions for someone expected to have an independent view.
Would you build the ML platform or buy it?
What they are looking for: Whether you weigh maintenance, not just capability.
Buy the undifferentiated parts and build what is actually specific to us. Open stacks exist for pipelines, training and tuning, and their stated point is letting teams run at scale without deep Kubernetes expertise, so rebuilding that is paying twice. I would build where our data or latency shape is genuinely unusual. The decision I would weigh hardest is the one nobody asks about: who maintains it in three years.
Make it yours: Raise the maintenance cost unprompted. It is the part build advocates leave out.
How would you get a model approved in a regulated environment?
What they are looking for: Whether you can work with a review process rather than around it.
Start from the framework the reviewers use. NIST's is voluntary and organised as govern, map, measure and manage, so I would prepare the documentation it asks for: what the model is for and what it is not, what data trained it and where that data came from, how performance is measured including across groups, and what the monitoring and rollback plan is. Having lineage from the registry makes most of that an export rather than an essay.
Make it yours: Cite a named framework. Vague talk about responsible AI does not survive an audit question.
Inference spend has tripled in a quarter. How do you bring it down?
What they are looking for: Commercial judgement, which is increasingly what separates senior candidates.
Attribute it first, by model and by caller, because it is usually one route. Then batching and utilisation, since idle accelerators are the common waste and GPU utilisation is a standard serving metric. Then whether every call needs the large model, routing easy cases to a cheaper one. Then caching. If the spend is genuinely load-driven and the unit economics do not work, that is a product and pricing conversation, not an engineering one.
Make it yours: Attribute before optimising. A candidate who starts compressing models has skipped the cheap win.
What kinds of technical debt are specific to machine learning systems?
What they are looking for: Whether you know this is a named, studied problem.
Entanglement, where changing one feature changes everything downstream. Boundary erosion, where the model's abstraction leaks into the rest of the system. Undeclared consumers, where a team you have never met depends on your output. And feedback loops, where the model's predictions shape the data it is retrained on. The warning in the original paper is that the fast early gains make all of this look free.
Make it yours: Give feedback loops a concrete example. It is the one candidates recite without understanding.
Why Machine Learning Engineers Need to Stay Informed
New AI models, MLOps tools, and deployment technologies are reshaping machine learning engineering. Staying current on ML frameworks, model optimization, and AI infrastructure helps engineers build reliable systems, improve performance, and advance their careers.
Read more
The practical reason is build or buy. Serving, orchestration and evaluation tooling turns over fast enough that a component you were about to write for a quarter is often a managed service by the time you finish scoping it, and finding that out late is the expensive version.
The bottom line
ML Technology Moves Fast. Stay Ahead.
Frameworks have an expiry date and systems judgement does not. Build the second deliberately, because knowing how data reaches a model, how it reaches it differently in production, and how you would find out is the part of this job that outlives every stack you will deploy on.
Stay Informed with Hark's Machine Learning Engineer Briefing
How it works
Curated from the best newsletters
Hark's editorial team handpicks the sources worth following. See how we rank
Distilled into one briefing
Six sources become a single five-minute read of what actually changed.
Texted to you every morning
It arrives before your first standup, at a time you choose.
Links back to the original
Every item names its source, so you can read the full piece when it matters.
The 6 Machine Learning Newsletters We Handpicked
TLDR AI
TLDR
- Free
- Daily (weekdays)
- 1.1M readers
TLDR's daily AI edition compresses research papers, product launches, and industry news into a five-minute weekday read for over a million subscribers.
Why machine learning engineers read it
Weekday compression of papers, launches and tooling news in about five minutes, which is the cheapest way to notice that something you were about to build now exists.
More about this newsletter
TLDR AI compresses the day's AI research, product launches, and industry news into one-sentence summaries you can scan in minutes. It is the most technical of the big AI dailies, written with engineers in mind. Efficient, dense, and no-nonsense.
The Batch
DeepLearning.AI (Andrew Ng)
- Free
- Weekly
Andrew Ng's weekly letter plus carefully explained AI news from the DeepLearning.AI team.
Why machine learning engineers read it
Andrew Ng's weekly letter from DeepLearning.AI, and the best source here for why a result matters rather than just that it happened. Strong on the engineering consequences of research.
More about this newsletter
The Batch, from Andrew Ng's DeepLearning.AI, covers the week's AI developments with an educator's clarity, opening with a personal letter from Ng himself. It is measured, credible, and accessible to practitioners and newcomers alike. AI news from one of the field's most influential teachers.
See the other 4 newsletters
Interconnects
Nathan Lambert (Substack)
- Freemium
- 1-2x weekly
- 79k readers
AI research newsletter by Nathan Lambert of the Allen Institute for AI, covering frontier-lab developments, open-source models, and post-training techniques without hype.
Why machine learning engineers read it
Nathan Lambert's deep technical writing on model training, post-training and open weights. The source to read when you need to understand how a model was actually made.
More about this newsletter
Essays on what is actually happening inside frontier AI labs, with a focus on open-source models, RLHF, and post-training. Lambert is a senior research scientist and post-training lead at the Allen Institute for AI (Ai2), so the analysis comes from someone who trains models for a living. A companion podcast accompanies many posts; paid subscribers ($15/mo or $150/yr) get extras like Discord access.
Best for: Readers who want frontier-model research from inside the arena. Working researcher Nathan Lambert reports on how leading models are trained and evaluated, technical but readable.
Latent Space
swyx & Alessio Fanelli
- Free
- 1-3x weekly (irregular)
- 197k readers
swyx and Alessio Fanelli's newsletter and podcast for AI engineers, covering models, tooling, and the craft of building with LLMs in production.
Why machine learning engineers read it
Practitioner-level coverage of the AI engineering stack: serving, inference cost, evaluation and the tools teams are really running in production.
More about this newsletter
swyx and Alessio Fanelli write for the AI engineer: the person building products on top of models. The newsletter and podcast cover tooling, techniques, and interviews with the people shipping the frontier. It named and defined the AI engineering discipline.
Best for: AI engineers and technical builders who want depth on how frontier systems are actually built. swyx and Alessio go deep on architecture, tooling, and the people building the models, well beyond surface-level news.
Ben's Bites
Ben Tossell
- Freemium
- Daily
- 170k readers
Ben Tossell's daily builder-focused AI newsletter tracking product launches, tools, and startup activity with a link-forward format.
Why machine learning engineers read it
A fast daily scan of launches and funding across the AI tooling market, useful for spotting infrastructure vendors before a procurement conversation reaches you.
More about this newsletter
Ben Tossell's daily is built for people making things with AI: product launches, tools, funding, and tutorials in a quick link-forward format. It grew up alongside the post-ChatGPT builder wave. The paid tier adds deep dives on how real companies use AI.
Best for: Founders, product people, and anyone building with AI. Ben Tossell's daily is written for people shipping things, pairing the news with the tools, launches, and practical angles a builder cares about.
MLOps Community Newsletter
MLOps Community
- Free
- Weekly
Weekly newsletter from the MLOps Community with technical deep dives, tooling insights, and practitioner stories about running ML and AI in production.
Why machine learning engineers read it
The practitioner community for exactly this discipline: pipelines, deployment, monitoring and the production war stories that do not get written up anywhere else.
More about this newsletter
The MLOps Community describes itself as a global network of over 70,000 AI and ML practitioners shaping how AI goes into production. Its weekly email mixes technical deep dives, tool insights, and practitioner war stories (including 'complete disasters'), plus memes. Signup runs through the community's join page at gatewaze.mlops.community.
You May Also Like
- Data EngineersThe upstream half of this job, where feature pipelines and warehouse design are built, and where most production model failures turn out to have started.
- Data ScientistsPartners on method and measurement, with the fastest projected growth of any occupation on this page's salary ladder at 35 percent to 2035.
- DevOps and Site Reliability EngineersWhere the deployment, monitoring and on-call discipline comes from, applied to services whose correctness is a distribution rather than a test result.
- AI ProfessionalsA wider view of the field, covering research, applied and product roles, and the likeliest place to look if the method end appeals more than the infrastructure.
Frequently Asked Questions
Entry-Level
What does a machine learning engineer do?
Builds and runs the system around a model. Day to day that means the pipelines that produce training data, the training runs that produce weights, the service that answers live requests inside a latency budget, and the monitoring that catches the model going quietly stale. The model itself is usually the smallest piece of it. The distinguishing duty is owning something whose behaviour was learned from data rather than written down, which makes data lineage and retraining engineering problems rather than afterthoughts.
How do you become a machine learning engineer?
Most people arrive from software engineering or from data science. A bachelor's degree is the typical entry-level education BLS lists for both software developers and data scientists. The reliable move is to take something you trained and actually deploy it: a pipeline that reruns, a service that answers requests, a dashboard that would tell you if it broke. That artefact answers the question every interview is really asking, which is whether you have run a model rather than only fitted one.
Is machine learning engineering a good career?
The surrounding occupations are growing well above average, data scientists at a projected 35 percent to 2035 and computer and information research scientists at 22 percent, and software developer pay sits at a $135,980 median for May 2025. The case against is churn in the tooling and the fact that a lot of the work is unglamorous plumbing nobody demos. The durable part is systems judgement, which survives every change of framework.
What is the difference between a machine learning engineer and an AI engineer?
Who owns the weights. An AI engineer builds at the application layer on top of a hosted model and owns prompts, retrieval, tool calls and the product surface, usually without training anything. A machine learning engineer owns the model's own lifecycle: the training data, the runs, the registry, the serving layer and the retraining loop. The two roles increasingly sit on the same team, and the seam between them is where training-serving skew and cost surprises tend to live.
What is the difference between a machine learning engineer and a data scientist?
Direction of travel. BLS describes data scientists as developing algorithms and models, then testing them for accuracy as new data arrives, which is analysis and method selection. A machine learning engineer takes that and makes it a system that runs without anybody present: scheduled, versioned, monitored and rollback-able. The overlap is real, and plenty of data scientists with a strong engineering background do both, which BLS also notes.
Do you need a degree to become a machine learning engineer?
A bachelor's degree is the typical entry-level education BLS records for software developers and data scientists, and it remains the common path. It is not a licence, and there is no certifying body, so a portfolio of deployed work substitutes more readily here than in a regulated profession. The graduate degree belongs to the research track: a master's is the typical entry-level education for computer and information research scientists, not for this role.
Do you need a master's degree or PhD to work in machine learning engineering?
Not for the engineering seat. BLS lists a bachelor's degree as the typical entry-level education for both software developers and data scientists, which is where most of this work is counted. A master's is the typical entry-level education for computer and information research scientists, a 38,600-job occupation at a $140,300 median in May 2025, and that is the research track rather than this one. A doctorate earns its keep if you want to produce methods rather than operate them; it buys very little on a team whose open problems are feature consistency, retraining cost and latency.
What programming languages should machine learning engineers learn?
Python and SQL are the working pair, and Google Cloud's machine learning engineer certification states candidates should be able to interpret both even though it does not directly assess coding. Beyond them it depends on the serving side: a compiled language where latency is tight, and enough shell, YAML and infrastructure configuration to live in Kubernetes. Languages matter less here than the surrounding craft of packaging, testing and dependency management.
Mid-Level
What are the most important skills for machine learning engineers?
Production-grade Python and data modelling, because most model problems are data problems. Pipeline orchestration so training can be rerun rather than remembered. Feature consistency between training and serving, which is the single most common production failure. Experiment tracking and a model registry so a deployed model traces back to the run that made it. Serving skills: latency, batching, utilisation and cost. Then monitoring for drift, which is the one teams skip and regret.
How much do machine learning engineers earn?
There is no federal occupation for the title, so the published anchors are indirect. Software developers had a $135,980 median in May 2025, computer and information research scientists $140,300, database architects $139,500 and data scientists $120,230. Computer and information systems managers, where engineering leadership is counted, were at $175,140. Machine learning roles at large technology companies generally sit above those medians once equity is counted, and none of the federal figures include equity.
What are the best entry-level jobs in machine learning engineering?
Data engineering on a team that already serves models, because the pipeline is where most of the real failures are. Backend engineering on an inference service, which teaches latency and capacity from the inside. Junior machine learning engineer where one exists, usually at a company with an established platform. Analytics engineering or applied data science, which builds the data instinct. All four put you next to a production model, which is the thing a portfolio project cannot simulate.
Can software engineers transition into machine learning engineering?
It is the most common route in, and software engineers usually start ahead rather than behind. The production skills, testing, packaging, deployment and monitoring, are exactly what machine learning teams are short of. What has to be added is data intuition and comfort with a component that is right most of the time: evaluating accuracy on held-out data, recognising drift, and accepting that a correct deployment can still be serving a wrong model.
What is the typical machine learning engineer career path?
Junior machine learning or data engineer, then machine learning engineer owning a model end to end, then senior, then a fork between staff or principal engineering and management. The lateral moves are real: applied machine learning, platform and MLOps, and data engineering all trade people freely. Management is counted separately in the federal data as computer and information systems managers, where five years or more of related experience is typical and the May 2025 median was $175,140.
What machine learning projects should you include in your portfolio?
One that is deployed and still running beats three that stop at a trained model. Make it a pipeline rather than a script, so the training step can be rerun with parameters instead of remembered. Register the model so the version being served traces back to the run that produced it, which is exactly what a model registry's versioning, stage management and lineage tracking exist for. Compute one feature in a single place and read it from both the training job and the serving path, then say in the README that this is how you avoid training-serving skew. Add drift monitoring on an input distribution and a rollback path. A reviewer will spend two minutes on it, and those are the five things they look for.
Which machine learning certifications are worth pursuing?
Three map closely to the work. AWS Certified Machine Learning Engineer, Associate expects roughly a year of hands-on machine learning engineering plus a year on AWS. Google Cloud's Professional Machine Learning Engineer expects three or more years of industry experience and tests serving, scaling, pipeline orchestration and monitoring over a two-hour exam. Databricks Certified Machine Learning Associate is 48 questions in 90 minutes, valid two years, with model deployment at 12 percent. None substitutes for deployed work.
What is MLOps, and why is it important for machine learning engineers?
MLOps is the practice of automating and monitoring the machine learning lifecycle the way DevOps did for software. Google Cloud describes three maturity levels: level 0 is manual and script-driven with no continuous integration and no active performance monitoring, level 1 automates the pipeline so the model is continuously retrained with data and model validation built in, and level 2 adds CI/CD for the pipelines themselves. It matters because a model that cannot be retrained cheaply will not be retrained at all.
Senior-Level
How do machine learning engineers deploy models into production?
The trained model is registered with a version and lineage, packaged behind a service, and released through the same CI/CD discipline as any other software, usually shadowed or canaried before it takes real traffic. The serving layer is specialised: inference servers offer dynamic batching and concurrent model execution and report throughput, latency and accelerator utilisation. The part that distinguishes a good deployment is that the feature code running at request time is the same code that ran in training.
What tools and frameworks do machine learning engineers use?
A training framework such as PyTorch or TensorFlow, an experiment tracker and model registry such as MLflow for versioning, stage management and lineage, a pipeline and platform layer such as Kubeflow on Kubernetes with Pipelines, Trainer and Katib for tuning, and an inference server such as NVIDIA Triton that supports TensorRT, PyTorch, ONNX and Python backends. Around all of it sits the ordinary stack: containers, CI/CD, a warehouse and whatever the cloud provider is.
How do machine learning engineers monitor and improve model performance?
By watching inputs and outputs, not just uptime. Feature distributions are monitored because concept drift, significant change in the data distribution, shows up there before the metrics move. Outputs are compared against delayed ground truth where it exists and against proxies where it does not. Improvement then runs through continuous training: a drift or quality threshold triggers a retrain, validation gates decide whether the new model is better, and a rollback path exists for when it is not.
How do you prepare for a machine learning engineer interview?
Bring one model you put into production and be able to describe its data path end to end, including what broke. Expect a systems design round about serving: latency, batching, capacity and cost, not just architecture. Expect a debugging question about a model that performs offline and fails live, where training-serving skew is the expected answer. Revise the data side, because SQL and pipeline questions catch more candidates than the modelling ones.
What are common machine learning engineer interview questions?
Design a system that serves this model to a million requests a day. A model scores well offline and badly in production, where do you look. How often should this be retrained and what triggers it. How do you keep training and serving features consistent. Walk through taking a notebook to production. What is specific about technical debt in machine learning systems. Most of them test the system around the model rather than the model.
How are LLMs and generative AI changing machine learning engineering?
They have moved some work up to the application layer, where calling a hosted model replaced training a small one, and moved far more work into serving: accelerator capacity, batching, caching, retrieval indexes, evaluation harnesses and a per-request cost that is now a line item somebody defends. Fine-tuning and preference training are pipeline problems of exactly the familiar shape. The classical work has not gone away either, since ranking, forecasting and fraud still run on trained models.
What are the biggest challenges in building production machine learning systems?
The documented ones have not changed much: entanglement, where changing one feature changes everything downstream, boundary erosion between the model and the rest of the system, undeclared consumers depending on an output you did not publish, and feedback loops where predictions become tomorrow's training data. Add training-serving skew, decay that ordinary monitoring misses, and the fact that the fast early gains make all of this look free until it is not.
How can machine learning engineers advance into senior engineering or technical leadership roles?
Two ladders, and the fork usually arrives around seven years. The staff and principal route rewards scope that other engineers depend on: platform interfaces, the standard a model must meet before it takes production traffic, and the build-or-buy calls whose real cost is who maintains the thing in three years. The management route is a different occupation in the federal data, computer and information systems managers, where BLS lists five years or more of related work experience as typical, across 685,800 jobs growing 16 percent to 2035 at a $175,140 median in May 2025. What moves people up either ladder is the same: owning the parts of the lifecycle nobody volunteers for, retraining automation, cost attribution and model governance, then writing the standard down so it survives you.
Get Tomorrow's Machine Learning Briefing
Six sources, one briefing, five minutes a morning. Enough to know whether the training infrastructure you were about to write became somebody's product last Tuesday.