Data Engineer Career Guide
Explore data engineering jobs, salaries, and career paths. Get interview tips and stay current on pipelines, warehouse and lakehouse architecture, AI, and industry trends.
The Top Data Engineering News, in 5 Minutes.
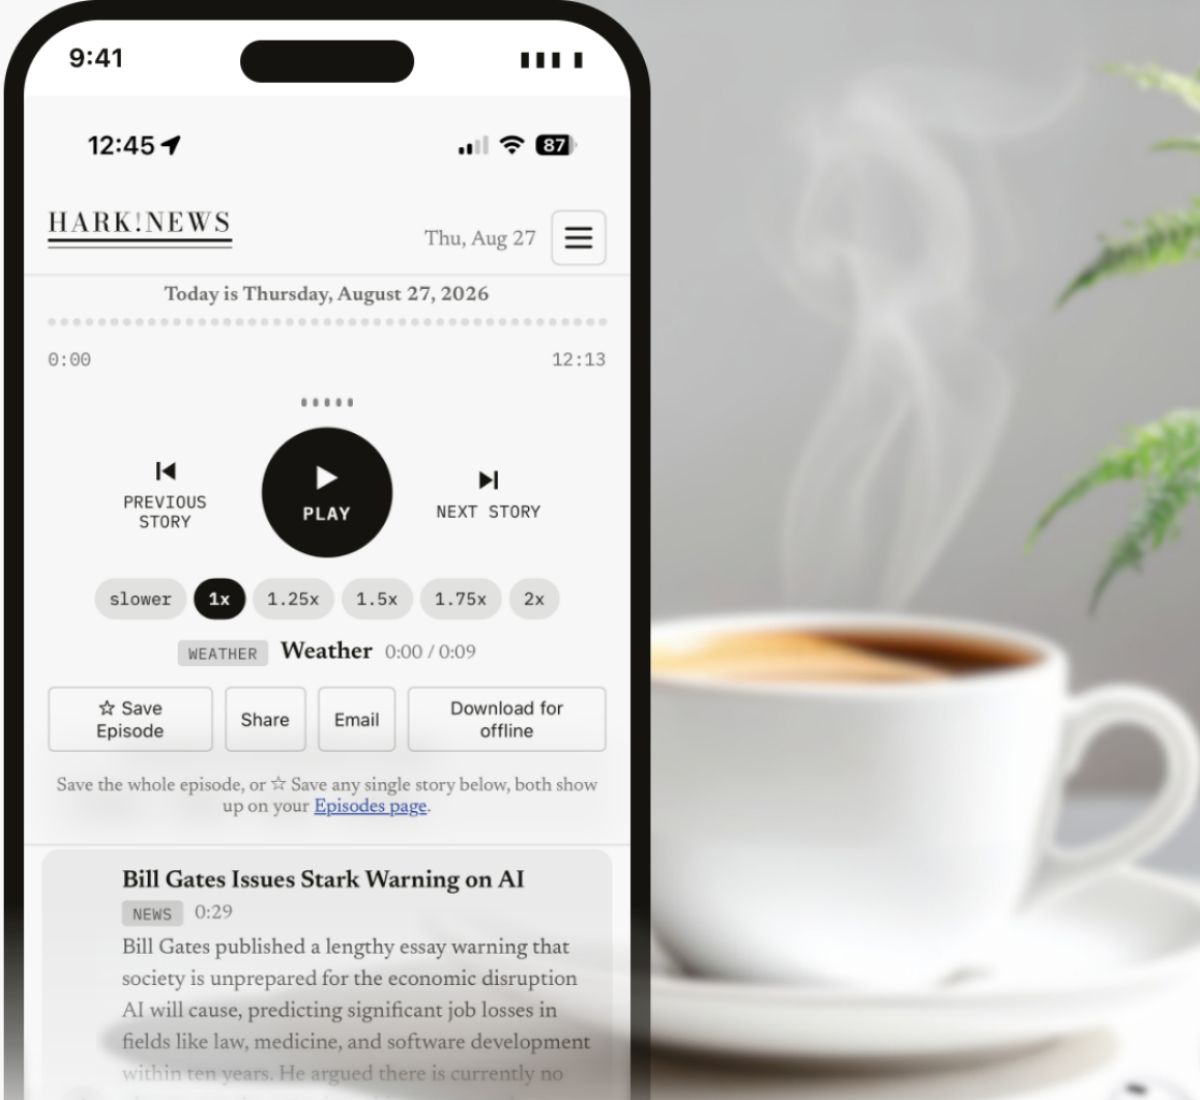
We handpick the best data engineering newsletters and distill the latest news and industry trends into a 5-minute audio briefing, texted to you every morning.
Try Our Data Engineering BriefingFreeSee the 6 newsletters we handpicked
At a glance
Data Engineering at a Glance
Roughly 144,500 people work in the United States as database administrators and architects, and that number understates the field badly, because data engineering has no federal occupation code of its own. The work is counted across several: database architects at a median of $139,500, database administrators at $104,620, software developers at $135,980, data scientists at $120,230, and the managers who run all of them at $175,140.
The job extends well beyond writing SQL, which is the misconception worth correcting early. Data engineers build ingestion from systems they do not control, model raw records into tables a business can reason about, orchestrate it all on a schedule, and own what happens when a source changes shape without warning. Analytics engineers specialise in the transformation layer between raw and reporting; data platform engineers build the tooling other data engineers use; reliability and governance roles exist at larger companies.
Pay rises fastest for people who can model a domain rather than operate a tool, which is also the skill that transfers between employers. Entry is unusually open: a bachelor's degree is typical rather than required, and the field hires from analytics and from backend engineering about as often as from computer science. The direction of travel is set by cheap object storage with open table formats on one side and AI on the other, and AI has mostly raised demand, because a model is only as good as the data behind it.
The numbers that matter
$139,500
Median annual pay for database architects (May 2025)U.S. Bureau of Labor Statistics
144,500
Database administrator and architect jobs in the United States (2025)U.S. Bureau of Labor Statistics
+35%
Projected growth for data scientists, 2025 to 2035U.S. Bureau of Labor Statistics
$175,140
Median annual pay for computer and information systems managers (May 2025)U.S. Bureau of Labor Statistics
Job titles
- Data Engineer
- Analytics Engineer
- Senior Data Engineer
- Data Platform Engineer
- Staff Data Engineer
- Head of Data Engineering
Who hires
- Technology companies
- Banks and insurers
- Retail and ecommerce
- Healthcare systems
- Consultancies
- Any company adopting AI
Credentials
- Bachelor's degree (typical, not required)
- Cloud data engineering certification
- Strong SQL
- Python
- A public pipeline project
- Infrastructure as code
Where data engineering careers are built
Ingestion
Getting data out of systems you do not control, reliably.
Modelling and transformation
Turning raw records into tables that mean something.
Orchestration
Scheduling, dependencies and what happens on a failure.
Platform
The tooling other data engineers build on. Where scale goes.
Quality and governance
Tests, lineage, access and deletion. The unglamorous half.
Cost and performance
Cloud bills are a design output, not an accident.
Data Engineering Jobs & Salaries
Data engineering has no federal occupation code, so the table below uses the codes the work is actually recorded under. They are not one ladder: a data engineer's pay typically sits between the database and the software developer rows, and the highest median in the field belongs to the people managing it.
Database administrators
$104,620
Data scientists
$120,230
Software developers
$135,980
Database architects
$139,500
Computer and information systems managers
$175,140
Source: US Bureau of Labor Statistics, Occupational Outlook Handbook (May 2025 pay, 2025 to 2035 projections), May 2025 pay data.
Data Engineering Career Paths
Three ladders that start from the same early years. The split comes where you decide whether your leverage is the model of the business, the platform other engineers build on, or the people. All three pay well, and only the last involves giving up the code.
- Analytics Engineer0 to 2 yearsThe transformation layer, in SQL, with tests
- Data Engineer2 to 5 yearsIngestion, orchestration and owning a domain
- Senior Data Engineer5 to 9 yearsSystems and their failure modes, including inherited ones
- Staff Data Engineer9 or more yearsDecisions that remove whole classes of problem
Credential that fits A cloud data engineering certification reads well; strong SQL and a public project read better
The salary table uses federal occupation codes because data engineering does not have one. A working data engineer's pay usually sits between the database administrator and software developer rows, which is why the table shows a range rather than a ladder.
A Typical Day in Data Engineering Jobs
Four roles that cover most of the field's headcount, ordered from the most junior to the most senior. The schedules are representative composites rather than one person's diary.
Analytics EngineerEntry-LevelLives in the transformation layer, turning raw tables into ones people can trust.
- 9:00Check which models failed overnight and why
- 9:30Add a column an analyst needs, and the test that protects it
- 11:00Review a colleague's pull request properly, not just approve it
- 13:00Work out why two dashboards disagree about one number
- 15:00Document the model, because nobody else will
- 16:30Ship, watch the run, go home
Data EngineerMid-LevelOwns ingestion and orchestration for a domain, including the parts that break.
- 8:30Triage the overnight failures, most of which are an upstream change
- 9:30Message the team that changed the schema without telling anyone
- 10:30Build the new connector, idempotent, with a replay path
- 13:00Pair with an analyst who needs the grain explained, not the table
- 15:00Look at the one job that has got slower every week for a month
- 16:30Write the runbook entry for the thing that broke last Tuesday
Senior Data EngineerSenior-LevelOwns systems rather than pipelines, and is the person asked whether this is a good idea.
- 8:00Read the overnight alerts and decide which ones should not exist
- 9:00Design review for an ingestion pattern three teams will copy
- 11:00Pull the warehouse spend report and find the two jobs that are the bill
- 13:00Mentoring, which at this level is mostly asking better questions
- 14:30Negotiate a data contract with the team that owns the source
- 16:00Write the migration proposal, including what it will cost to not do it
Head of Data EngineeringSenior-LevelDecides what the team builds, what it stops, and what it refuses.
- 7:30Read the industry writing, because the vendor roadmap is not a strategy
- 9:00Roadmap conversation with a stakeholder who wants everything by March
- 10:30One-to-ones, which at this level are mostly retention
- 13:00Platform review: what to standardise, what to let teams choose
- 15:00Budget, and the awkward conversation about the warehouse bill
- 16:30Hiring loop debrief, and a decision nobody on the panel wanted to make
Job guide
How to Get a Data Engineering Job in 2026
What the work asks of you, the skills employers screen for, and the questions you will be asked. The three tabs split the same guide by experience, because what gets an analytics engineer hired is not what gets a staff engineer hired.
Entry-Level
Breaking Into Data Engineering
The way in is almost never an advert for a data engineer. It is an analytics or backend role where you take the pipeline work nobody wants, plus one project that looks like the job.
What to Know About the Field
The facts that should shape your first applications.
A Computer Science Degree Is Typical, Not Required
BLS lists a bachelor's degree as typical entry for both the database and the software developer codes, and the field has always hired on demonstrated work as much as on a transcript. The real barrier for analysts moving across is not SQL, which they have, but software engineering practice: version control, testing, review, and writing something a stranger can run.
Sources: US Bureau of Labor Statistics, Database Administrators and ArchitectsUS Bureau of Labor Statistics, Software Developers, Quality Assurance Analysts, and Testers
Data Engineering Has No Occupation Code of Its Own
The federal data counts the work across several: 144,500 database administrators and architects at a median of $126,760, 1.9 million software developers at $134,040, 275,600 data scientists at $120,230, and 685,800 computer and information systems managers at $175,140. A data engineer's pay typically sits between the database and developer rows, which is why salary research on this title is so inconsistent.
Sources: US Bureau of Labor Statistics, Database Administrators and ArchitectsUS Bureau of Labor Statistics, Software Developers, Quality Assurance Analysts, and TestersUS Bureau of Labor Statistics, Data ScientistsUS Bureau of Labor Statistics, Computer and Information Systems Managers
The Growth Is Real, and Uneven
Database administrators and architects are projected to grow 4 percent to 2035 with about 7,300 openings a year, software developers 10 percent with 106,100 openings, and data scientists 35 percent with 24,800. The spread matters when you choose a title to aim at, because the slower code is the one most associated with operating existing systems rather than building new ones.
Sources: US Bureau of Labor Statistics, Database Administrators and ArchitectsUS Bureau of Labor Statistics, Software Developers, Quality Assurance Analysts, and TestersUS Bureau of Labor Statistics, Data Scientists
Silent Failure Is the Discipline's Defining Problem
A broken service pages somebody. A broken pipeline produces a wrong number that somebody believes. Everything distinctive about data engineering practice, idempotency, data tests, lineage, contracts with upstream teams, exists because the usual signal that something is wrong does not fire here.
Source: US Bureau of Labor Statistics, Database Administrators and Architects
Skills Employers Hire For
What actually gets a first data engineering job.
SQL, Past the Interview Level
Window functions, the grain of a join, and reading a query plan well enough to say why something is slow. It is the language of the job and the part of the interview most candidates underestimate.
Python as the Glue
Not data science Python. Connectors, tests, small services, and code another person can run next year. Readability beats cleverness in a codebase that is mostly maintained by whoever is on call.
One Cloud Platform, End to End
Storage, warehouse, identity, networking and billing on a single provider, rather than three platforms at tutorial depth. Depth transfers; a list of logos does not.
Testing the Data, Not Just the Code
Row counts, nulls, uniqueness, referential checks and freshness, running with the pipeline. These catch the failures that do not throw an exception, which is most of them.
Interview Questions and Answers
What you will be asked as a junior or a career changer.
Write a query to find each user's most recent order.
What they are looking for: Whether your SQL goes past GROUP BY.
A window function partitioned by user and ordered by date, then filter to row number one. I would check whether ties are possible before shipping it.
Make it yours: Name the tie case before they ask. That single sentence reads as production experience.
How do you decide the grain of a table?
What they are looking for: Modelling instinct, which is hard to fake.
From the question it has to answer and the key that uniquely identifies a row. If I cannot state in one sentence what one row means, the model is not finished.
Make it yours: Use that one-sentence test out loud. Interviewers remember it.
A pipeline ran successfully and the numbers are wrong. What now?
What they are looking for: Systematic debugging under silent failure.
Confirm the report is wrong before changing anything, then compare counts at each stage against the source to find the step where the number diverges. Nine times out of ten it is an upstream change or a join that is fanning out.
Make it yours: Lead with verifying the claim. Candidates who start changing code look dangerous.
What does this team page on?
What they are looking for: This one is yours to ask them.
The answer tells you whether alerting is tied to data expectations or to job exit codes, which predicts what your nights look like better than any other question.
Make it yours: Follow it with how often. A team that cannot answer has not measured.
Mid-Level
Advancing as a Data Engineer
The middle is where you stop being handed requirements and start negotiating them. Modelling judgement, cost awareness and the ability to say no to real-time are what separate this rung from the one below it.
What to Know About the Field
What shapes the move from building to owning.
Silent Failure Is the Discipline's Defining Problem
A broken service pages somebody. A broken pipeline produces a wrong number that somebody believes. Everything distinctive about data engineering practice, idempotency, data tests, lineage, contracts with upstream teams, exists because the usual signal that something is wrong does not fire here.
Source: US Bureau of Labor Statistics, Database Administrators and Architects
The Growth Is Real, and Uneven
Database administrators and architects are projected to grow 4 percent to 2035 with about 7,300 openings a year, software developers 10 percent with 106,100 openings, and data scientists 35 percent with 24,800. The spread matters when you choose a title to aim at, because the slower code is the one most associated with operating existing systems rather than building new ones.
Sources: US Bureau of Labor Statistics, Database Administrators and ArchitectsUS Bureau of Labor Statistics, Software Developers, Quality Assurance Analysts, and TestersUS Bureau of Labor Statistics, Data Scientists
The Pay Rises Fastest Away From the Tools
Computer and information systems managers have the highest median in the field at $175,140, with five years or more of related experience listed as typical entry. The adjacent analytical codes sit lower: operations research analysts at $88,940, data scientists at $120,230. The money follows the people who decide what gets built rather than the people fluent in a particular tool.
Sources: US Bureau of Labor Statistics, Computer and Information Systems ManagersUS Bureau of Labor Statistics, Operations Research AnalystsUS Bureau of Labor Statistics, Data Scientists
A Computer Science Degree Is Typical, Not Required
BLS lists a bachelor's degree as typical entry for both the database and the software developer codes, and the field has always hired on demonstrated work as much as on a transcript. The real barrier for analysts moving across is not SQL, which they have, but software engineering practice: version control, testing, review, and writing something a stranger can run.
Sources: US Bureau of Labor Statistics, Database Administrators and ArchitectsUS Bureau of Labor Statistics, Software Developers, Quality Assurance Analysts, and Testers
Skills Employers Hire For
What hiring managers read at this level.
Data Modelling
Deciding what one row means and what you promise about it. The most durable skill in the field, the one that transfers between employers, and the one no tool chooses for you.
Orchestration and Idempotency
Scheduling, dependencies, retries and the property that makes a rerun safe. Idempotency alone converts most pipeline incidents from an outage into a retry.
Cost as a Design Input
In cloud warehouses the billing model is part of the architecture. The engineer who understands it can do things nobody else can afford, and is also the one who finds the two jobs that are the bill.
Negotiating With Upstream Teams
Most incidents start as a schema change somebody shipped without knowing you existed. The fix is social before it is technical: a contract, an owner and a warning, agreed in advance.
Interview Questions and Answers
What a mid-level loop turns on.
Design ingestion for a source with late and duplicate records.
What they are looking for: Idempotency, grain, and what happens on a replay.
I define the natural key and the grain first, upsert rather than append, keep an ingestion timestamp separate from the event timestamp, and make the whole job safe to rerun for any window.
Make it yours: Say the word idempotent and then show it, with the replay case worked through.
Batch or streaming for this requirement?
What they are looking for: Whether you push back on real-time.
I ask what decision gets made with the data and how quickly. Most requests for real-time are requests for data that is not a day old, which a more frequent batch solves at a fraction of the operational cost.
Make it yours: Have one example where you chose batch and one where streaming was genuinely required.
Tell me about an incident you owned.
What they are looking for: Ownership, and whether it recurred.
A source changed a field type overnight. I noticed from a freshness alert, backfilled four days, then added a schema test and agreed a contract with that team. It has not happened again.
Make it yours: End with the change that stopped it recurring. Without that it is just a story.
How would you cut our warehouse bill by a third?
What they are looking for: Whether you measure before optimising.
Find the handful of jobs that are most of the spend, because they always are. Then incremental instead of full refresh, partition on what is actually filtered, and delete the scheduled jobs nobody reads.
Make it yours: The last one is the best answer and almost nobody gives it.
Senior-Level
Leading in Data Engineering
Senior work is measured in problems that stopped happening. The choice at this point is whether your leverage is the platform, the model of the business, or the people, and all three require writing things down.
What to Know About the Field
What the senior market rewards.
The Pay Rises Fastest Away From the Tools
Computer and information systems managers have the highest median in the field at $175,140, with five years or more of related experience listed as typical entry. The adjacent analytical codes sit lower: operations research analysts at $88,940, data scientists at $120,230. The money follows the people who decide what gets built rather than the people fluent in a particular tool.
Sources: US Bureau of Labor Statistics, Computer and Information Systems ManagersUS Bureau of Labor Statistics, Operations Research AnalystsUS Bureau of Labor Statistics, Data Scientists
Silent Failure Is the Discipline's Defining Problem
A broken service pages somebody. A broken pipeline produces a wrong number that somebody believes. Everything distinctive about data engineering practice, idempotency, data tests, lineage, contracts with upstream teams, exists because the usual signal that something is wrong does not fire here.
Source: US Bureau of Labor Statistics, Database Administrators and Architects
Data Engineering Has No Occupation Code of Its Own
The federal data counts the work across several: 144,500 database administrators and architects at a median of $126,760, 1.9 million software developers at $134,040, 275,600 data scientists at $120,230, and 685,800 computer and information systems managers at $175,140. A data engineer's pay typically sits between the database and developer rows, which is why salary research on this title is so inconsistent.
Sources: US Bureau of Labor Statistics, Database Administrators and ArchitectsUS Bureau of Labor Statistics, Software Developers, Quality Assurance Analysts, and TestersUS Bureau of Labor Statistics, Data ScientistsUS Bureau of Labor Statistics, Computer and Information Systems Managers
The Growth Is Real, and Uneven
Database administrators and architects are projected to grow 4 percent to 2035 with about 7,300 openings a year, software developers 10 percent with 106,100 openings, and data scientists 35 percent with 24,800. The spread matters when you choose a title to aim at, because the slower code is the one most associated with operating existing systems rather than building new ones.
Sources: US Bureau of Labor Statistics, Database Administrators and ArchitectsUS Bureau of Labor Statistics, Software Developers, Quality Assurance Analysts, and TestersUS Bureau of Labor Statistics, Data Scientists
Skills Employers Hire For
What a staff or lead search screens for.
Data Modelling
Deciding what one row means and what you promise about it. The most durable skill in the field, the one that transfers between employers, and the one no tool chooses for you.
Cost as a Design Input
In cloud warehouses the billing model is part of the architecture. The engineer who understands it can do things nobody else can afford, and is also the one who finds the two jobs that are the bill.
Negotiating With Upstream Teams
Most incidents start as a schema change somebody shipped without knowing you existed. The fix is social before it is technical: a contract, an owner and a warning, agreed in advance.
Orchestration and Idempotency
Scheduling, dependencies, retries and the property that makes a rerun safe. Idempotency alone converts most pipeline incidents from an outage into a retry.
Interview Questions and Answers
What a staff or leadership panel asks.
What would you standardise across a team of eight?
What they are looking for: Senior thinking about leverage.
The modelling convention, a testing floor, one orchestration pattern and the review bar. Then make the paved road the easy path rather than the mandated one.
Make it yours: Distinguish standards that prevent incidents from standards that are taste.
Warehouse, lake or lakehouse, and why?
What they are looking for: Whether you can state a trade-off.
The real question is who owns the schema and when. A warehouse makes you pay the modelling cost up front; a lake lets you defer it and then charges you repeatedly.
Make it yours: Answer with the trade-off, not the product. Naming a vendor first is a tell.
How would you cut our warehouse bill by a third?
What they are looking for: Whether you measure before optimising.
Find the handful of jobs that are most of the spend, because they always are. Then incremental instead of full refresh, partition on what is actually filtered, and delete the scheduled jobs nobody reads.
Make it yours: The last one is the best answer and almost nobody gives it.
Tell me about an incident you owned.
What they are looking for: Ownership, and whether it recurred.
A source changed a field type overnight. I noticed from a freshness alert, backfilled four days, then added a schema test and agreed a contract with that team. It has not happened again.
Make it yours: End with the change that stopped it recurring. Without that it is just a story.
Why Data Engineers Need to Stay Informed
AI, cloud technologies, and new data tools are reshaping the data engineering industry. Staying informed helps data engineers adopt emerging technologies, make smarter technical decisions, and build the skills needed to stay competitive and advance their careers.
The bottom line
Data Engineering Is Evolving. Keep Your Edge.
The occupations this work is recorded under are growing between 4 and 35 percent to 2035, and the demand behind that is simple: organisations cannot use AI on data they have not organised. The engineers who do well are the ones who learn the architecture lessons from other people's write-ups rather than from their own outages.
Stay Informed with Hark's Data Engineering Briefing
How it works
Pick the newsletters you want
Choose from our handpicked list, or add your own. See the picks
We subscribe you properly
Each one arrives at your own private Hark address, never your inbox.
We read them so you do not have to
Every issue is distilled into one short script each morning.
You listen on the way in
A text arrives with a link. Five minutes, then you are current.
The 6 Data Engineering Newsletters We Handpicked
Data Engineering Weekly
Ananth Packkildurai
- Free
- Weekly
Weekly roundup of data engineering articles, tools, and industry news curated by Ananth Packkildurai.
Why data engineers read it
The field's weekly reading list, and the closest thing it has to a journal of record: architecture write-ups, post-mortems and papers, curated by someone who reads them.
More about this newsletter
A Substack-hosted weekly digest of notable data engineering reading (pipelines, platforms, and ecosystem news) curated with brief commentary by data engineering practitioner Ananth Packkildurai. It is free and has drawn public praise from industry figures for its weekly roundups.
TLDR Data
TLDR (TLDR Media)
- Free
- Mon, Thurs
- 590k readers
Data science and data engineering news, tools, and deep dives, twice a week in a quick read.
Why data engineers read it
Five minutes of headlines across data, AI and the vendors. The fastest way to notice something is happening before you decide whether to care.
More about this newsletter
TLDR Data curates deep dives, tools, and trends across data engineering and data science in the TLDR house style of tight summaries with links. The site says 82 percent of readers are data scientists and engineers, and it claims to be the largest data newsletter anywhere. Best for data practitioners who want a fast, curated scan rather than daily volume.
See the other 4 newsletters
The Analytics Engineering Roundup
dbt Labs (Tristan Handy)
- Free
- 31k readers
Curated links and commentary on analytics engineering and the modern data stack, written by dbt Labs founder Tristan Handy and colleagues.
Why data engineers read it
Covers the transformation layer specifically, which is where most data engineering work has moved and where the modelling arguments actually happen.
More about this newsletter
Tristan Handy, founder and CEO of dbt Labs, curates the internet's most useful articles on analytics engineering and its adjacent ecosystem, with added commentary. Hosted on Substack at a dbt Labs domain, it is free and claims over 31,000 subscribers.
SeattleDataGuy's Newsletter
Ben Rogojan
- Free
- Weekly
Practical data engineering from a working consultant: pipeline and warehouse design, the tool choices behind them, and career advice for people building data platforms.
Why data engineers read it
Practical and consultant-flavoured, strongest on the parts nobody teaches: scoping, cost, and why the stack a company has is the stack it can afford to run.
More about this newsletter
One of the few data engineering reads that covers the career as well as the craft, from someone who consults across enough companies to compare them.
Best for: Data engineers who want practitioner judgement on tooling and architecture, plus candid career advice.
DataTalks.Club Newsletter
DataTalks.Club (Alexey Grigorev)
- Free
- Weekly
Weekly community newsletter from DataTalks.Club, Alexey Grigorev's global online community of data science, ML, and AI practitioners.
Why data engineers read it
Community-driven, and the best of the six on learning paths and open projects. Useful when you are trying to get in rather than already in.
More about this newsletter
DataTalks.Club runs free courses (its Zoomcamps), podcasts, and events for a community it describes as 130,000+ data and AI professionals, and the weekly newsletter keeps subscribers informed about everything happening in the club. Signup is an email field with a Join button on the homepage.
Joe Reis
Joe Reis
- Free
- Weekly-ish
Essays on data engineering practice from the co-author of Fundamentals of Data Engineering: lifecycle thinking, data modelling, and a recurring scepticism about tool hype.
Why data engineers read it
Opinionated writing on data modelling and where the discipline is drifting. The one that argues with the consensus rather than summarising it.
More about this newsletter
Wrote the book much of the field learned from, and uses the newsletter to argue with the industry rather than summarise it.
Best for: Data engineers who want first-principles argument about the discipline, not a tool roundup.
You May Also Like
- Data ScientistsThe team your pipelines feed, and the federal code growing fastest in this field at 35 percent to 2035. Many data engineers arrive from here or leave for it.
- Software EngineersWhere most data engineering postings are counted by the government, and the discipline whose practices separate a pipeline that lasts from one that is rebuilt annually.
- DevOps & SREReliability engineering applied to services rather than data. The closest neighbouring craft, and the source of most of the on-call thinking this job borrows.
- AI ProfessionalsModel work downstream of everything you build. Worth reading because retrieval quality and model quality both bottom out as a data problem on your side of the line.
Frequently Asked Questions
Entry-Level
What does a data engineer do, and what does a typical workday look like?
A data engineer builds and runs the systems that move data from where it is created to where it is used, and is accountable for it arriving correct and on time. A typical day is less glamorous than the job title suggests: check the overnight pipeline runs and work the failures, extend a model to carry a column some analyst needs, review a colleague's pull request, and spend an hour on the one job that has quietly been getting slower for a month. The work is software engineering with a particular failure mode, which is that your bugs are usually silent. A broken service pages someone; a broken pipeline just produces a number that is wrong, and someone believes it.
Is data engineering a good career, and what is the long-term job outlook?
The federal data does not record data engineering as its own occupation, so the honest answer uses the codes the work sits inside. Database administrators and architects number 144,500 and grow 4 percent to 2035, data scientists number 275,600 and grow 35 percent, software developers number 1.9 million and grow 10 percent. The direction is good across all three and only one is a star. What should shape your expectations is less the growth rate than the structural fact underneath it: every company that wants to use AI first has to get its own data in order, and almost none of them have.
How do you become a data engineer, and do you need a computer science degree?
Most data engineers arrive sideways, from analytics, from backend engineering, or from a data-adjacent operations job. A computer science degree helps and is not a requirement: BLS lists a bachelor's degree as typical entry for both the database and the software developer codes, and the field's hiring has always leaned on demonstrable work. What is genuinely required is real software engineering practice. The gap that stops analysts becoming data engineers is not SQL, which they already have, but version control, testing, code review and the habit of writing something another person can run.
What skills and programming languages do you need to become a data engineer?
SQL first, properly, including window functions and query plans, because it is the language of the job and the thing interviews actually test. Then Python, which is the glue for everything else. Then one cloud platform end to end rather than three superficially, SQL-based transformation tooling, workflow orchestration, and enough Linux and networking not to be helpless. Learn one columnar warehouse deeply. Spark and streaming are worth having but are not where a first job is won, and a candidate with excellent SQL and clean Python beats one with a longer tool list every time.
What is the difference between a data engineer, data analyst, data scientist, and analytics engineer?
Four roles on one spectrum, divided by how far from the raw source you work. Data engineers own ingestion, storage and the pipelines, and write mostly code. Analytics engineers own the transformation layer between raw tables and the ones analysts query, and write mostly SQL; the role barely existed ten years ago and is now the most common bridge between the other two. Data analysts answer business questions with the resulting tables. Data scientists build models and run experiments on them. The boundaries move by company size: at a startup one person does all four, at a bank each is a department.
What are the best entry-level jobs and career paths into data engineering?
The three reliable routes in are an analytics or business intelligence role where you push into the transformation layer, a junior backend or platform engineering role where you take the data work nobody wants, and a graduate data engineering programme at a company large enough to run one. All three beat applying cold for a mid-level opening. Titles worth searching that are really entry-level data engineering: analytics engineer, BI developer, data platform associate, and ETL developer at older employers.
Which certifications, courses, and portfolio projects help you break into data engineering?
Certifications matter less here than in most of IT, with one exception: the cloud providers' data engineering credentials are recognised and do get a resume read, particularly by larger employers and consultancies. What moves a hiring manager more is a project that looks like the job rather than like a course. One end-to-end pipeline that ingests a real source on a schedule, tests its own output, and is documented well enough for a stranger to run it will outperform five tutorial notebooks.
Mid-Level
How much do data engineers earn at entry, mid-career, and senior levels?
The federal codes the work is recorded under give the honest range, because data engineering has none of its own. Database administrators sit at a median of $104,620 and database architects at $139,500, software developers at $135,980, data scientists at $120,230, and computer and information systems managers at $175,140. In practice an analytics or junior data engineer tends to start below the database administrator figure, a mid-career data engineer lands between the administrator and developer rows, and senior and staff engineers at large technology employers sit at or above the architect figure once equity is counted.
How do you prepare for a data engineering technical interview?
Expect two or three technical rounds plus a design conversation. SQL will be live and harder than you think, usually a window function problem and a question about why a query is slow. Python will be a data manipulation exercise with edge cases in the input. The pipeline design round is the one that decides it: you will be asked to design ingestion for a source with late and duplicate records, and the answer they want is idempotency, a clear grain, and what happens on a replay. Prepare one incident in detail, told as what broke, how you noticed, what you changed, and how you stopped it recurring.
What tools and technologies should every data engineer know?
A columnar warehouse, SQL transformation tooling, an orchestrator, a cloud object store, infrastructure as code, and a version control and CI setup you can configure rather than just use. Add one streaming system and one processing engine for large data. Underneath the tools the durable knowledge is data modelling, the distinction between batch and streaming semantics, partitioning, and cost: in cloud warehouses the person who understands the billing model is usually the person who can do things nobody else can afford.
What is the difference between data engineering, cloud engineering, and data platform engineering?
Data engineering owns the movement and the modelling of data. Cloud engineering owns the infrastructure under it, networking, identity, compute, and does not care much what flows through. Data platform engineering is the overlap, and is what the data engineering role becomes at scale: building the orchestration, the catalogue, the lineage and the self-service tooling that other data engineers use. Platform work pays better, is further from the business question, and is where the job goes if you stay technical.
How do you design reliable, scalable data pipelines and ETL/ELT workflows?
Start from the grain and the contract, not the tool. Decide what one row means and what guarantees you offer about it, then design backwards. Make every step idempotent so a rerun is safe, which is the single property that converts most pipeline incidents from an outage into a retry. Separate ingestion from transformation so a schema change upstream breaks one thing. Test the data, not just the code: row counts, nulls, uniqueness and referential checks catch the failures that do not throw.
How do you choose between batch processing, streaming, and real-time data architectures?
Batch unless something forces otherwise, and the thing that forces otherwise is a decision that has to be made within seconds. Streaming multiplies the operational burden, the cost and the number of ways correctness can go wrong, and most requests for real-time data turn out on questioning to be a request for data that is not twenty-four hours old, which a more frequent batch solves. When streaming is genuinely required, be explicit about event time versus processing time, late arrivals and exactly-once semantics, because those three are where the real complexity lives.
How do data engineers ensure data quality, security, governance, and regulatory compliance?
Quality is engineering: tests that run with the pipeline, defined expectations, and alerts a human actually reads. Governance is organisational: a catalogue, documented ownership, lineage so a change can be traced to what it breaks. Security is access control at the column and row level, encryption, and the discipline of not copying production data into places it cannot be governed. Compliance adds deletion and residency obligations, which have to be designed into the model rather than retrofitted, because honouring a deletion request across a lake of denormalised copies is close to impossible if nobody planned for it.
Senior-Level
How is AI changing data engineering jobs, skills, and responsibilities?
AI has raised demand for this work far more than it has automated it, because a model is only as good as the data behind it and most organisations discovered their data was not ready. Assistants are genuinely useful for the mechanical parts, boilerplate, first-draft SQL, documentation and tests, which is real time saved. What they do not do is decide the grain, negotiate a contract with the team upstream or own the incident at 3am. The federal projections around the field are growth rather than decline: data scientists 35 percent to 2035, software developers 10 percent.
How do you advance from data engineer to senior, staff, or principal data engineer?
By owning things rather than tickets. The step to senior is reliably about a system and its failure modes being yours, including the parts you did not build. Staff and principal go further: you are measured on decisions that remove whole classes of problem, a model everyone else builds on, a platform choice that lasts five years, a standard that makes the next twenty pipelines boring. The visible marker is that your work is increasingly written down and increasingly about other teams, and the ratio of your time spent in code falls without your influence falling with it.
What are the most important architectural trade-offs when choosing data warehouses, data lakes, and lakehouses?
A warehouse gives you performance, governance and a query optimiser, at the cost of structure imposed up front and vendor gravity. A lake gives you cheap storage and any file type, at the cost of being something rather than nothing only because of the discipline you apply. The lakehouse puts a table format over object storage to get warehouse semantics on lake economics, and is now the default for new builds at scale. The real trade is who owns the schema and when: pay the modelling cost early in a warehouse, or late and repeatedly in a lake.
How do experienced data engineers optimize pipeline performance, reliability, and cloud costs?
Measure first, because intuition about distributed systems is usually wrong. Most warehouse cost sits in a handful of jobs, so find them before optimising anything. Then the standard levers: partition and cluster on what is actually filtered, prune columns, stop full refreshes that could be incremental, and look hard at the scheduled jobs nobody reads the output of, which is frequently the cheapest saving available. For reliability, idempotency and retries first, then backfill tooling, then alerting tied to data expectations rather than to job exit codes.
How do you transition from a technical data engineering role into engineering management or leadership?
By deciding, deliberately, that your contribution becomes other people's output. The failure mode is the manager who is still the best engineer on the team and keeps proving it, which caps the team at their throughput. Practise before the title: run the incident review, mentor two juniors, own the roadmap conversation with a stakeholder. BLS lists five years or more of related experience as typical entry for computer and information systems managers, which sits at a median of $175,140, above every individual contributor code the field uses.
How should data engineering leaders build teams, establish standards, and measure performance?
Standards first, because a team without them produces N styles of pipeline and 10N ways to break. Agree the modelling convention, the testing floor, the orchestration pattern and the review bar, then make the paved road the easiest path rather than the mandated one. Measure what a user of the data would notice: freshness against a stated target, the rate of failed runs, time to restore after an incident, and cost per workload. Resist measuring tickets closed or pipelines built, which rewards accumulation, and accumulation is the thing that eventually makes a data platform unmaintainable.
How should CTOs and data executives develop a data engineering strategy that supports AI adoption and business growth?
Start from what the business will decide with data, not from an architecture diagram. The strategy that survives contact is usually dull: a small number of trusted datasets, clear ownership, governance that works in practice, and a platform people can self-serve from. AI makes this more urgent rather than different, because retrieval and model quality both bottom out in the same data quality problem. Be explicit about what you will not build, and budget for the unglamorous half, documentation, lineage, deletion and access control, which is where most ambitious data strategies quietly fail.
Get Tomorrow's Data Engineer Briefing
The warehouse migration your company is about to start was written up last month by someone who finished it.